

Pricing and product documentation checked on October 29, 2026. This Datadog review uses published vendor material and publicly accessible screenshots, not an authenticated customer account. Features, service quotas and billing terms can change. See the official Datadog pricing source before buying.
Datadog offers broad infrastructure and application observability, but buyers need to understand host-based products, log indexing, traces, metrics and add-ons before drawing a meaningful total-cost figure. The Datadog review treats monitoring as an operational system with several billing units. Host coverage, indexed logs, spans, metric cardinality and on-call ownership are more useful evaluation inputs than the number of built-in dashboards.
This Datadog review looks at the operational cost of combining infrastructure hosts, APM, log indexing and metrics. The purchasing decision should follow a representative incident and the separate quantities charged for each product.
Some DigiOffly links may earn a commission at no added cost to readers. Published vendor features and price terms are examined independently of those links.
📊 Datadog Review Summary
Datadog aggregates infrastructure signals, application traces and logs across services. Teams need to decide which signals shorten incident investigation and how much it will cost to ingest, retain and search them. Host counts and log events must not be treated as one billing unit.
💰 Datadog plans at a glance
| Plan | Official entry price | What to verify |
|---|---|---|
| Infrastructure Pro | From $15/host/month annually | Host monitoring and integrations |
| Infrastructure Enterprise | From $23/host/month annually | Advanced infrastructure features |
| APM | From $31/APM host/month annually | Distributed tracing, subject to product combinations |
| Logs | Metered | Ingestion and indexing charges vary by volume and retention |
⚡ Verdict & Monitoring Scope
An operations team may monitor several cloud services with Datadog yet still struggle to identify which alert matters. The review should measure whether its broad telemetry helps locate the service owner and explain user impact.
One place for heterogeneous telemetry
Datadog combines metrics, traces, logs and many integrations, but a large tool inventory does not ensure alerts correspond to customer impact. Datadog infrastructure monitoring provides host-level context, but a dashboard without an incident runbook does not fix failures.
Consolidating metrics, logs, traces, and infrastructure integrations into a single platform eliminates tool-switching friction during outages, yet a sprawling telemetry inventory rarely guarantees that alerts map directly to actual customer impact. When engineers monitor everything indiscriminately, diagnostic noise drowns out genuine anomalies, leading to alert fatigue and delayed incident triage. Routine logs from a noisy service can bury a connection-pool warning. Index what engineers need for diagnosis rather than every debug message. This integration suite is most useful for teams managing complex distributed architectures where cross-domain correlation is mandatory for root-cause analysis. Before committing to a broad ingestion contract, a buyer must verify how metric-to-trace linking operates under high load, whether index retention policies prevent runaway storage costs, and if ingestion filters can be applied upstream to drop redundant telemetry before processing begins.
Choosing an observability footprint
A team may start with infrastructure and add APM, logs or RUM only where the operational question cannot be answered otherwise.
Deploying every available observability module from day one introduces severe budget friction without proportional operational clarity, meaning teams should strategically adopt infrastructure monitoring first and layer on APM, logs, or Real User Monitoring only when specific diagnostic questions demand deeper visibility. An unconstrained rollout often causes billing spikes because unstructured log ingestion scales unpredictably alongside user traffic growth. One risk involves enabling full-fidelity log indexing across staging and production environments alike, resulting in excessive expenditure for telemetry data that engineering teams never review during active incidents. This targeted adoption strategy proves exceptionally useful for growing engineering organizations balancing tight cloud budgets against strict SLA requirements. When evaluating licensing options, a procurement team should verify pricing tiers for Infrastructure Pro versus Enterprise, map exact anticipated host counts, and confirm how metered log volumes are calculated against contractual commitments before signing multi-year agreements.
What a dashboard cannot replace
Incident response requires service ownership, runbooks and deploy awareness. Correlated graphs cannot make organizational decisions.
No amount of sophisticated charting or automated graph correlation can substitute for clear service ownership, rigorous runbooks, and active deployment awareness during a critical production outage. When an unexpected regression brings down a core payment gateway, static dashboards merely display the symptom without dictating which engineering squad holds immediate remediation responsibility or how to safely roll back the offending artifact. A frequent organizational failure mode occurs when teams assume that publishing a real-time metrics screen fulfills their operational readiness obligations, leaving responders stranded without documented mitigation steps when core dependencies fail. This operational discipline is most useful for mature engineering cultures transitioning from monolithic systems to decentralized microservice architectures. Prospective enterprise buyers must verify that their chosen tooling integrates effectively with internal on-call rotas and incident management systems rather than relying on monitoring screens to drive human accountability.
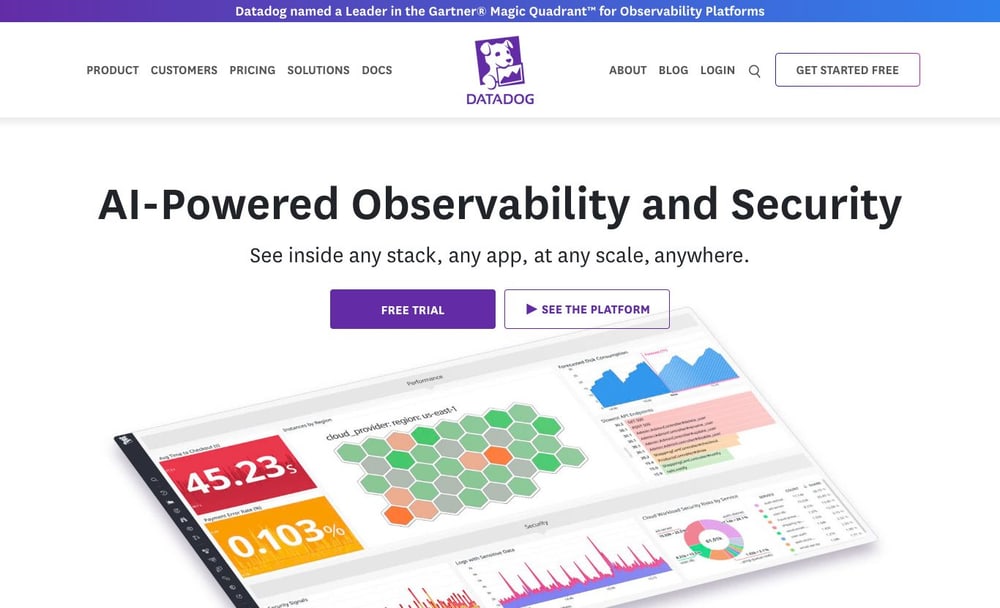
📈 Infrastructure Monitoring
Infrastructure hosts, containers and integrations have different resource boundaries. A Kubernetes node scaling down does not necessarily remove the telemetry dimensions already indexed under a custom metric.
Hosts, containers and integrations
Infrastructure Pro and Enterprise use host-based pricing, with container or other usage considerations depending on product. Map ephemeral resources carefully. Datadog database monitoring can help connect slow queries to host saturation when the proper integration and tags are enabled.
Managing infrastructure costs under host-based pricing models like those in Infrastructure Pro and Enterprise requires careful accounting of ephemeral resources and rapid container scaling. Because modern container orchestration platforms dynamically spin up and terminate pods across underlying virtual machines, failing to map these dynamic units correctly can lead to unexpected billing multipliers that distort total cost projections. Autoscaling can add billable hosts. A sensible Datadog budget accounts for peak node counts rather than only idle infrastructure. This pricing structure is most useful for stable, predictable virtual machine fleets where physical host boundaries remain relatively static over long billing cycles. Buyers evaluating these plans must verify how container density factors into licensing tiers, whether short-lived jobs incur full host fees, and how automated resource discovery handles elastic cloud elasticity.
Cloud and Kubernetes labels
Tags make investigations easier but high-cardinality combinations can increase cost and complicate dashboards. Datadog network monitoring may explain cross-service latency that an application trace alone cannot isolate.
Implementing comprehensive cloud and Kubernetes labeling conventions accelerates multi-dimensional root-cause analysis, yet unconstrained tag propagation can rapidly introduce high-cardinality inflation that degrades dashboard rendering speed and bloats metric storage fees. When development teams append dynamic user identifiers or unique transaction tokens directly into telemetry tags, the monitoring backend generates millions of distinct time series for a single metric. A common operational failure mode involves applying unrestricted metadata schemas across Kubernetes clusters, creating sprawling custom dashboards that time out under load because every individual pod instance populates unique tag combinations. This labeling practice is most useful for organizations enforcing standardized taxonomy across multi-tenant cloud environments. Before adopting an expansive tagging policy, technical buyers must verify platform cardinality limits, understand index query performance impacts, and establish strict naming conventions to prevent uncontrolled dimensional expansion.
Alert thresholds and maintenance
Infrastructure alerts should represent symptoms or saturation with meaningful action. A red CPU chart alone is not an incident classification. Datadog anomaly detection needs a meaningful baseline, otherwise unusual but harmless traffic becomes alert noise.
Configuring infrastructure alerts to trigger strictly on user-facing symptoms or hard resource saturation rather than transient metric spikes prevents unnecessary pager noise and ensures every notification demands meaningful human intervention. A persistent red CPU utilization chart on a background worker node does not inherently constitute an active operational incident if underlying job queues continue processing normally without user impact. Problems arise when teams establish rigid static thresholds on volatile operating system metrics, resulting in cascading midnight alarms for brief CPU bursts during scheduled routine backups. This threshold strategy is exceptionally useful for on-call teams striving to minimize operational fatigue and protect system reliability. When designing alert workflows, technical buyers should verify notification routing flexibility, test anomaly detection capabilities against historical workloads, and ensure alert rules incorporate sustained duration windows before firing.
🔎 Traces & Application Performance
Distributed tracing can identify a slow database call only when trace propagation survives the application boundary. Sampling and service tags need to correspond to the incidents engineers actually investigate.
APM host definitions
APM may charge for hosts generating traces. Separate application visibility from the number of infrastructure hosts and confirm the product mix. Datadog APM pricing is metered differently from infrastructure hosts and should appear as a separate budget line.
Separating application performance monitoring host counts from core infrastructure measurements is essential for accurate budgeting because APM licensing often bills specifically for hosts generating active traces rather than physical servers alone. When enterprise software architectures decouple compute infrastructure from runtime application layers, miscalculating how many containers or serverless execution environments emit traces can cause unexpected contract overages. One risk involves assuming that purchasing an Infrastructure Enterprise license automatically covers APM trace ingestion for all deployed microservices, leading to surprise bill adjustments at the end of the quarter. This distinct product tiering is particularly useful for organizations running heterogeneous software stacks where only a subset of backend services requires deep distributed tracing. Before finalizing any commercial commitment, buyers must verify exact APM host definition criteria, review how multi-product bundle discounts apply, and confirm invoice calculation methods across all target environments.
Distributed traces and service maps
Trace propagation must survive asynchronous jobs and service boundaries. Broken correlation can make a seemingly complete map misleading. Datadog distributed tracing depends on propagating trace identifiers across the calls that make up a request.
Distributed tracing relies on rigorous context propagation across asynchronous queues, background workers, and multi-service boundaries to maintain end-to-end visibility. When an asynchronous job drops context headers or network boundaries strip trace flags, Datadog breaks the parent-child relationship, fragmenting the service map into isolated islands that make systemic bottlenecks look like independent errors. Teams often encounter broken correlation during HTTP header handoffs in microservice architectures or when message brokers strip custom metadata from payloads. This feature is indispensable for debugging latency regressions in distributed systems, particularly when diagnosing slow database queries hidden behind multiple service hops. Buyers should verify how SDKs handle automatic instrumentation for their specific language frameworks and asynchronous libraries, testing failure modes where downstream services fail or timeout to ensure trace continuity remains intact under load.
Profiles and sampled traces
Sampling can control volume, but may miss unusual failures. Decide what to retain for real investigations. Datadog log retention settings affect what engineers can investigate after an incident is reported late.
Application profiling paired with distributed trace sampling helps manage storage volume and compute overhead, but aggressive head-based or tail-based sampling configurations risk dropping critical diagnostic evidence for rare edge-case failures. When high-throughput services drop ninety-nine percent of routine spans, transient race conditions or intermittent memory leaks can disappear from the aggregated performance profile entirely. Teams rely on continuous profiling during high-traffic load testing and production incident post-mortems to pinpoint exact line-level CPU bottlenecks and allocation spikes without exhaustive manual tracing. Buyers must verify sampling rules, custom retention policies, and head-versus-tail sampling criteria to ensure that sporadic exceptions and long-tail latency spikes are preserved in storage, preventing blind spots where infrequent but severe system failures evade detection.
Workflow roles compared
| Capability | What Datadog contributes | What the team must own |
|---|---|---|
| APM host definitions | APM may charge for hosts generating traces. Separate application visibility from the number of infrastructure hosts and confirm the product mix. | Roles, test data, validation and escalation |
| Distributed traces and service maps | Trace propagation must survive asynchronous jobs and service boundaries. Broken correlation can make a seemingly complete map misleading. | Configuration review and failure handling |
| Profiles and sampled traces | Sampling can control volume, but may miss unusual failures. Decide what to retain for real investigations. | Access, recovery and documentation |
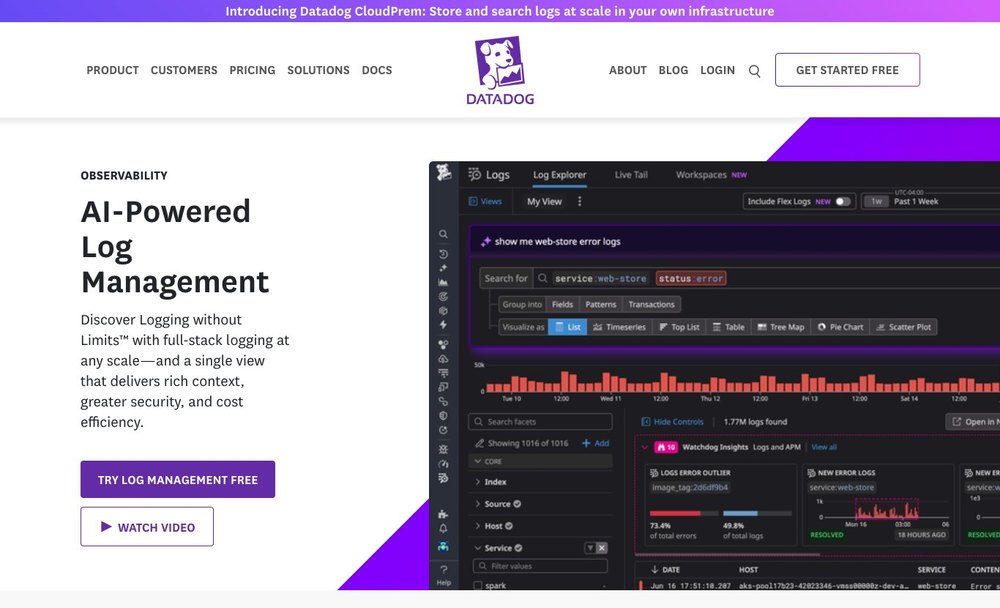
📋 Logs, Metrics & Retention
Log collection looks inexpensive at small volume until verbose debugging is enabled everywhere. Ingested and indexed data, retention and high-cardinality metrics each require a deliberate spending rule.
Ingest versus indexed logs
Datadog log costs can depend on both volume ingested and events indexed, plus retention. A storage policy affects the final bill. Datadog log management requires explicit decisions about which events to ingest, index and keep searchable.
Log management billing depends heavily on the operational split between ingested log volume, indexed events, and long-term retention tiers, meaning raw ingestion alone does not dictate total storage expenditure. Without strict indexing filters and selective parsing rules, teams frequently discover that retaining every standard output line across high-throughput clusters inflates monthly invoices unexpectedly. This capability is vital for compliance auditing, debugging complex runtime exceptions, and maintaining historical forensic data across distributed cloud environments. Buyers should verify how log retention policies, exclusion filters, and re-indexing mechanisms are configured within the platform interface, calculating ingestion versus indexing ratios before committing to high-volume log shipping agreements to prevent runaway storage costs.
Custom metrics and cardinality
Labels containing individual user IDs or request IDs can explode time-series counts. Design telemetry dimensions intentionally. Datadog log parsing can expose searchable fields, but uncontrolled tag values may increase telemetry costs.
Custom metrics and dimensional cardinality require disciplined tag design because attaching high-cardinality attributes like individual user IDs, dynamic session tokens, or unique request UUIDs to time-series data triggers exponential metric growth and licensing inflation. When services emit thousands of unique metric combinations per minute, time-series databases face severe query slowdowns and unexpected billing tier escalations. Teams use custom metrics to track application-specific Key Performance Indicators, business transactions, and queue depths in real-time production dashboards. Buyers must verify metric exclusion filters, tag aggregation rules, and cardinality monitoring tools within their alerting pipelines, ensuring developers sanitize dimensions before submission to maintain predictable performance and cost controls.
Security of logs and traces
Sanitize tokens, personal data and payment details before ingestion; apply appropriate retention and access permissions.
Log and trace payloads frequently ingest accidental secrets, bearer tokens, personally identifiable information, or raw financial data if developers fail to sanitize data streams at the collection edge. Unfiltered telemetry creates severe compliance vulnerabilities and violates data privacy mandates if restricted payloads become globally searchable across engineering dashboards. This security governance is critical for maintaining regulatory compliance under frameworks like GDPR or SOC 2 while retaining operational observability. Buyers must verify platform-level redaction rules, attribute scrubbing pipelines, Role-Based Access Control policies, and encryption keys to ensure unauthorized personnel cannot query sensitive production data stored within log and trace repositories.
💰 Pricing and Cost Modeling
Datadog Infrastructure Pro may begin at $15 per host under annual billing, but adding APM and indexed logs changes the calculation. A purchase model should separate each meter before aggregating a monthly estimate.
Infrastructure base pricing
Datadog Infrastructure Pro begins at $15 per host monthly with annual billing. On-demand rates differ and add-ons are not included automatically.
Datadog Infrastructure Pro starts at fifteen dollars per host monthly with annual commitments, establishing a baseline platform cost that excludes necessary APM modules, log indexing meters, synthetic monitoring tests, and cloud security add-ons. Relying solely on base infrastructure pricing creates inaccurate budget projections because supplementary telemetry products scale independently and quickly surpass the initial host fee. This tiered pricing model is standard for enterprise infrastructure monitoring where organizations scale virtual machine fleets, Kubernetes clusters, and serverless functions dynamically. Buyers must verify which specific integrations, container metrics, and auxiliary telemetry features are bundled within the base tier versus those requiring separate line-item add-ons before signing multi-year contracts.
APM and log charges
Datadog APM is listed from $31 per APM host monthly annually when combined with Infrastructure. Log indexing uses event and retention meters.
Datadog APM begins at thirty-one dollars per APM host monthly when bundled with annual Infrastructure commitments, while log indexing charges scale separately based on total ingested byte volume and retention duration. Combining APM and log management products introduces compound cost scaling where high-throughput services amplify both trace volume and indexing meters simultaneously. This pricing structure is essential for software organizations requiring deep application-level transaction tracing and centralized log analytics across microservices. Buyers should verify total cost simulations that combine base infrastructure counts, active APM host allocations, and projected log ingestion volumes to avoid unexpected budget overruns during traffic spikes or application scaling events.
Stack-wide budget guardrails
Estimate steady hosts, transient scaling, indexed events, custom metrics and outlier spikes separately. A small sample bill may understate production growth.
Budgeting for observability requires treating infrastructure hosting, distributed tracing, and log volumes as distinct cost vectors rather than a unified predictable subscription. Because Infrastructure Pro and Enterprise tiers bill baseline hosts monthly while APM and metered log indexing scale dynamically with traffic bursts, projecting expenses solely from a low-traffic staging environment invariably leads to severe monthly invoice surprises. Problems arise when an unexpected traffic surge forces autoscaling groups to spin up dozens of temporary nodes, multiplying base infrastructure fees while simultaneously flooding ingestion pipelines with unindexed or high-retention log data. Buyers should verify whether their teams have instituted strict log exclusion filters, metric drop rules, and quota alerts before production deployment. By separating baseline host calculations from erratic event-driven telemetry growth, finance and engineering leads can prevent runaway billing spikes that obscure the true return on investment of comprehensive system monitoring.
⚖️ Alternatives & Integration
Sentry often helps with exception triage while Datadog covers more of the surrounding infrastructure. Decide which product first receives a broken-release alert and who closes the incident after the application recovers.
Datadog versus Sentry
Datadog spans operations telemetry; Sentry has a developer-error perspective. Many teams can reduce overlap by defining different incident questions. Datadog incident management and Sentry issue triage solve overlapping but different parts of production response.
Choosing between broad operations tooling and dedicated error tracking requires clarifying whether an engineering organization needs macro-level infrastructure metrics or micro-level runtime exception details. Datadog excels at unifying host-level resource utilization, network performance, and distributed tracing across complex architectures, whereas Sentry focuses heavily on capturing stack traces, unhandled exceptions, and user-facing code bugs. One risk involves paying for both platforms to ingest duplicate application logs and performance traces without clear ownership boundaries, causing fragmented incident triage. Teams find Datadog useful when correlating database latency with server CPU bottlenecks, while Sentry remains indispensable for isolating specific syntax or null-pointer errors inside front-end and backend codebases. Buyers should verify how their developers route exceptions and infrastructure alerts to prevent redundant ingestion overhead and ensure each tool answers distinct operational questions.
Datadog with GitLab CI/CD
Linking deployment metadata to alerts can reveal whether a change preceded a regression. Confirm how CI tokens and release identifiers propagate.
Integrating continuous delivery pipelines with observability platforms bridges the gap between code releases and runtime performance degradation. When deployment markers and version identifiers from GitLab pipelines flow automatically into monitoring dashboards, engineers can instantly determine if a sudden error spike or memory leak correlates with a specific commit. A frequent implementation pitfall occurs when misconfigured CI tokens or unpropagated release tags cause deployment events to drop silently, leaving responders blind to recent code modifications during an incident. This integration proves exceptionally useful during high-frequency deployment cycles where manual release tracking is impossible. Buyers should verify that their CI runner scripts correctly inject immutable commit hashes and environment tags into monitoring payloads, ensuring that every alert contextualizes performance metrics against the exact code revision currently running in production.
Datadog with Railway
Observe app services deployed on Railway with clear service tags and an explicit sampling plan, rather than instrumenting every environment indiscriminately.
Monitoring containerized applications hosted on Platform-as-a-Service environments like Railway requires deliberate control over telemetry volume to prevent excessive overhead and unexpected subscription costs. Because platform-as-a-service setups often abstract away underlying host infrastructure, monitoring relies heavily on application performance monitoring libraries and container log forwarders rather than bare-metal agent installations. One risk is enabling 100 percent trace sampling and verbose logging across ephemeral preview environments and staging branches, which quickly inflates metered data bills without providing actionable production insights. Implementing clear service tags, environment filters, and selective trace sampling ensures that observability remains focused on customer-facing production workloads. Buyers should verify how their chosen APM libraries manage export buffers and whether log collection agents can be selectively disabled on non-critical development instances before rolling out instrumentation across all deployed services.
Alternatives and complements
| Software | Relationship to Datadog | Key question |
|---|---|---|
| Sentry | Alternative or complementary tool | Which exact workflow changes? |
| Railway | Alternative or complementary tool | Would this duplicate a paid function? |
| GitLab | Complementary part of stack | How are permissions and failures handed off? |
🧪 Pilot & Verdict
For a trial, correlate a deliberately slow endpoint with a CPU spike and its deployment ID. The useful result is a coherent incident trail, not a larger number of graphs in a dashboard.
Instrument one service thoroughly
Choose one business-critical service and one dependent database, then trace a controlled latency problem across both.
Executing a meaningful evaluation of an observability platform demands focusing initial setup on a single high-impact transaction path rather than attempting organization-wide instrumentation all at once. By selecting one business-critical microservice and its primary database dependency, teams can trace real request lifecycles, identify network bottlenecks, and evaluate distributed tracing accuracy without drowning in noise. A common failure mode during pilot phases is scattering basic agents across dozens of peripheral services, which yields fragmented telemetry and obscures how performance anomalies propagate through database connection pools. This focused approach proves particularly useful for testing APM overhead, custom metric collection, and dashboard responsiveness under controlled load testing conditions. Buyers should verify that their engineers can successfully isolate database query latency from application processing time within the chosen service before committing to wider architectural rollout plans.
Reconcile a cost estimate
Compare expected hosts, logs and APM usage against the actual trial bill. Investigate differences before expanding agent deployment.
Validating initial financial projections against actual billing data during a trial period is essential for preventing unexpected enterprise expenditures. Because software evaluations frequently start with minimal workloads, extrapolating future invoices without accounting for log ingestion multipliers and APM host add-ons often results in severe budgetary discrepancies. Problems arise when teams treat trial period invoices as static indicators, failing to notice how background health checks and custom metric generation silently drive up metered consumption. Reconciling estimated host counts and indexed log volumes against real billing statements is extremely useful for establishing baseline cost-per-service metrics prior to full-scale adoption. Buyers should verify that internal accounting teams have audited the trial usage breakdown to identify which specific telemetry streams contribute the highest volume charges before approving enterprise contracts.
Focus on operational outcomes
Datadog earns its complexity when it shortens diagnosis with accountable alerts. More telemetry is not necessarily more reliability.
Maximizing the value of an advanced observability platform requires shifting focus from raw metric collection volume to actionable incident resolution times. Simply gathering exhaustive logs and metrics across every server node does not inherently improve system reliability if alerting rules generate fatigue rather than precise diagnostic insights. One risk involves configuring broad, unweighted alert thresholds that notify on every minor CPU fluctuation, desensitizing on-call engineers and obscuring genuine production outages. Evaluating platform effectiveness based on how quickly responders can trace root causes and restore service proves vital for justifying complex tooling investments. Buyers should verify that their alerting framework is tied directly to user-facing service level objectives and actionable runbooks, ensuring that instrumentation actively streamlines debugging rather than simply accumulating unstructured telemetry data.
🏆 Final Verdict: Is Datadog Worth It?
Datadog can connect an infrastructure anomaly to an application trace and its logs. That is useful when engineers can follow the evidence without bouncing between unrelated alerts. Budget by monitored host, retained telemetry and the features the on-call team needs; adding every integration is rarely the best starting point.
For Datadog, trace an intentionally slow service request alongside host metrics and log records. Count the telemetry volume produced by the pilot before enabling it across an organization. The product earns its place when the response owner can diagnose the incident faster.

Frequently Asked Questions
What is Datadog used for?
Datadog supports hosts, containers and integrations and related developer workflows. Datadog offers broad infrastructure and application observability, but buyers need to understand host-based products, log indexing, traces, metrics and add-ons before drawing a meaningful total-cost figure. Compare its role in a complete software stack before choosing an annual plan.
Is there a Datadog free plan?
Datadog publishes the following plan starting points: Infrastructure Pro From $15/host/month annually, Infrastructure Enterprise From $23/host/month annually, APM From $31/APM host/month annually, Logs Metered. Free access and included services vary by workload; confirm the current official pricing page before relying on an allowance.
How much does Datadog cost in 2026?
Datadog pricing depends on the plan and service unit. Infrastructure Pro From $15/host/month annually, Infrastructure Enterprise From $23/host/month annually, APM From $31/APM host/month annually, Logs Metered. Additional usage, add-ons, seat count or infrastructure charges can change the total invoice. The vendor pricing page is linked in this review.
What are the key Datadog features?
Datadog focuses on apm host definitions, distributed traces and service maps, profiles and sampled traces. Availability and limits depend on the active offering, and not every advertised add-on is included in a standard plan.
Who should consider Datadog?
Datadog offers broad infrastructure and application observability, but buyers need to understand host-based products, log indexing, traces, metrics and add-ons before drawing a meaningful total-cost figure. A buyer should validate role permissions, a realistic workload and who maintains the connection after the initial setup.
How should a team evaluate Datadog security?
For Datadog, restrict API keys, dashboard access and sensitive log queries. Redact personal data before ingestion and test whether a limited operator can trace an alert to its origin.
What are Datadog alternatives?
Sentry concentrates on application errors; Grafana-based stacks may cover metrics and visualization. Datadog spans several observability products, so compare hosts, traces and logs separately.
Does Datadog integrate with other developer tools?
Datadog agents, cloud integrations and OpenTelemetry carry different signals. Align service names and tags so traces can be correlated with host metrics and relevant log records.
What are the limitations of Datadog?
Infrastructure hosts, APM hosts, log ingestion and indexing, retention and custom metrics can each affect costs. Measure one service’s data volume before scaling the estimate to a fleet.
How can a team migrate to Datadog?
Export dashboards and alert definitions where supported, then inventory agents, instrumentation and log pipelines. Keep old and new alert paths active during a staged cutover.
How was this Datadog review researched?
DigiOffly checked public Datadog pricing and product documentation on October 29, 2026. Screenshots show official publicly accessible pages. This article does not claim an authenticated company implementation or independently measured uptime.
EXPLORE NEXT ON DIGIOFFLY
🔍 Explore More on DigiOffly
Compare related developer platforms, estimate software costs and navigate DigiOffly guides before adding Datadog to a production stack.
Explore related software
- Development & DevOps — Explore all eight developer software categories and reviews.
- Hosting & Websites — Review hosting and infrastructure choices.
- Automation & No-Code — Find integration and workflow alternatives.
- Sentry review — Developer error monitoring
- Railway review — Application deployment and hosting
Compare your shortlist
- Software Directory — Browse reviewed tools by software category.
- Compare Software — Compare capabilities, billing and compatibility.
- AI Software Finder — Narrow options by your exact engineering workflow.
Plan costs and updates
- Software Cost Calculator — Estimate known license and usage costs.
- Best Value Advisor — Compare products against a practical requirement.
- Deal Alerts — Receive relevant software offers and updates.
- Vercel — Next.js deployment previews and commercial hosting costs
- Glassnode review — See historical market-data coverage and limitations